trafikisaret
DATASET BUILT FROM SCRATCHA Turkish traffic-sign dataset labelled from scratch on my own dashcam footage, and a two-stage recogniser trained on it. Stage one finds the boxes without caring about the class; stage two classifies each crop, and answers with a question mark when it is not sure. Kendi dashcam kayıtlarımdan sıfırdan etiketlenmiş bir Türk trafik işareti veri seti ve üzerinde eğitilmiş iki aşamalı bir tanıyıcı. Birinci aşama sınıfa bakmadan kutuları buluyor; ikinci aşama her kırpmayı sınıflandırıyor, emin olamadığında soru işaretiyle cevap veriyor.
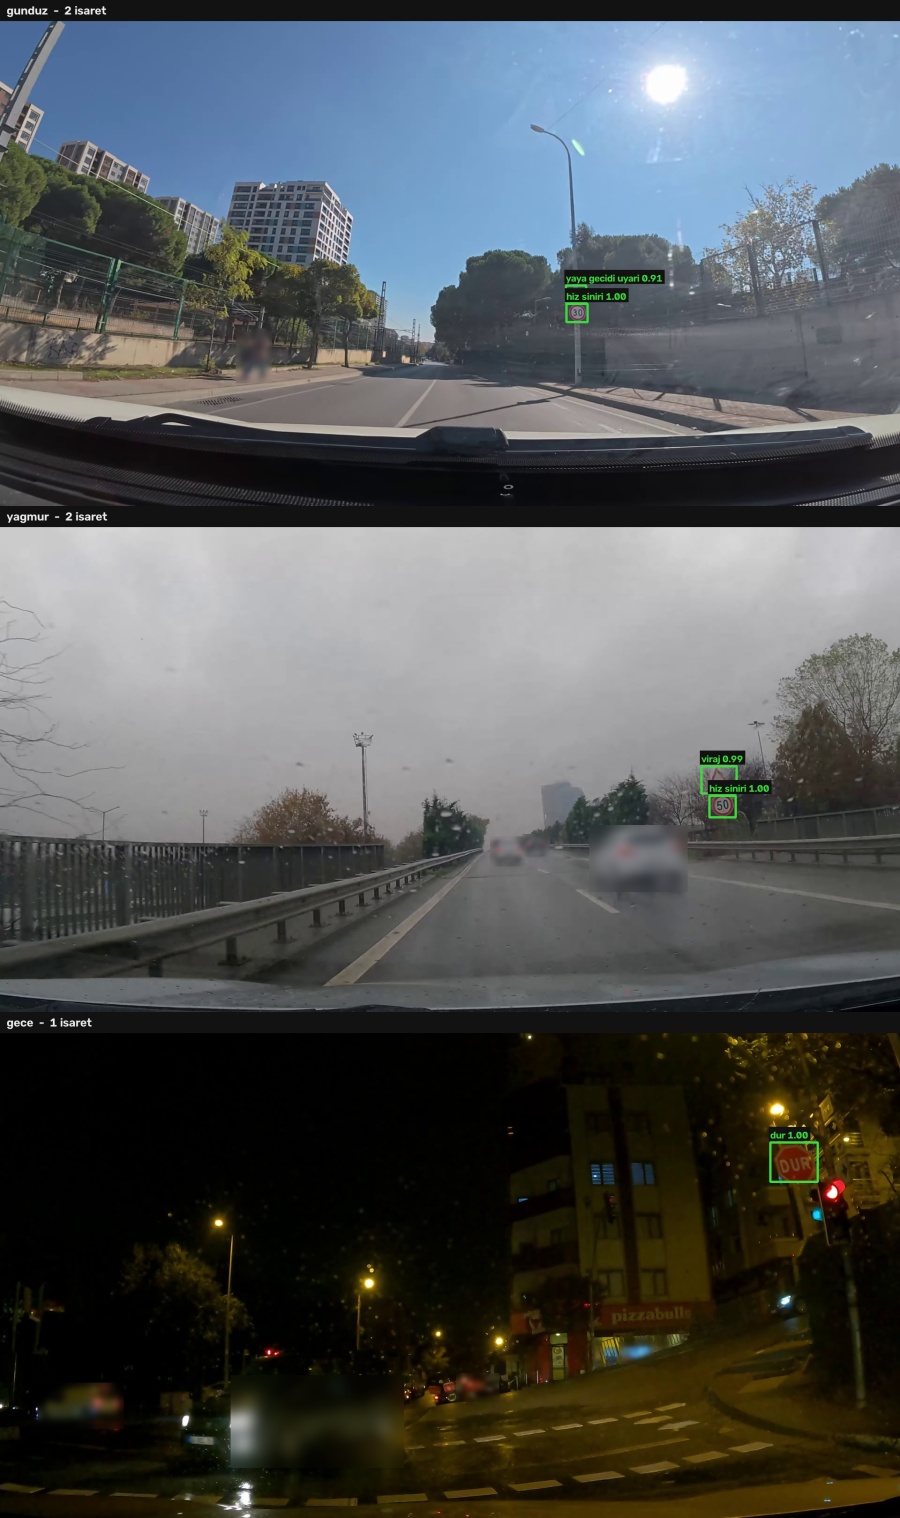
The same model on three conditions. The night frame finds exactly one sign, and it stays in the demo on purpose — the model is weak there and hiding it would make the demo a claim rather than a measurement. Aynı model üç koşulda. Gece karesinde tam olarak tek işaret bulunuyor ve bu bilerek demoda duruyor — model orada zayıf ve bunu gizlemek demoyu ölçüm olmaktan çıkarıp iddiaya çevirirdi.
The data decided the architectureMimariye veri karar verdi
One detector predicting 23 classes would have to learn each from an average of 31 boxes, and the thinnest class has 3. Collapsing every sign into a single class means all 717 boxes train the detector at once, and telling the classes apart becomes a separate crop-classification problem where each box is a training example in its own right. 23 sınıf tahmin eden tek bir dedektör, her sınıfı ortalama 31 kutudan öğrenmek zorunda kalırdı; en ince sınıfta 3 kutu var. Bütün levhaları tek sınıfta toplamak, 717 kutunun tamamının dedektörü aynı anda eğitmesi demek; sınıfları ayırmak da her kutunun başlı başına bir eğitim örneği olduğu ayrı bir kırpma sınıflandırma problemine kalıyor.
Classes below the threshold were not swept into an "other" bucket. Grouping visually unrelated signs under one label teaches the classifier a contradiction; if a class is unsupported, the repo says so. Eşiğin altında kalan sınıflar bir "diğer" kutusuna doldurulmadı. Görsel olarak alakasız levhaları tek etiket altında toplamak sınıflandırıcıya çelişki öğretir; bir sınıf desteklenmiyorsa repo bunu yazar.
MeasurementsÖlçümler
FROM THE TRAINING RUNS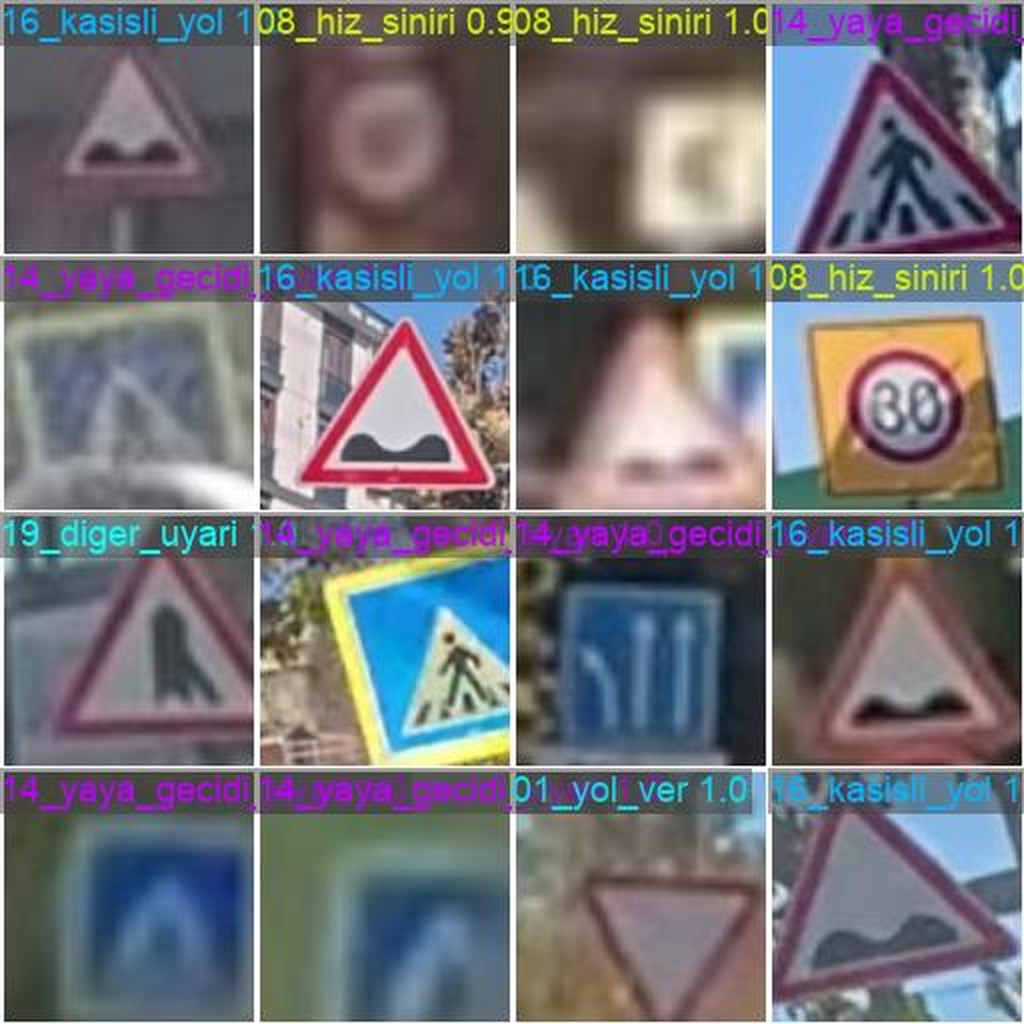
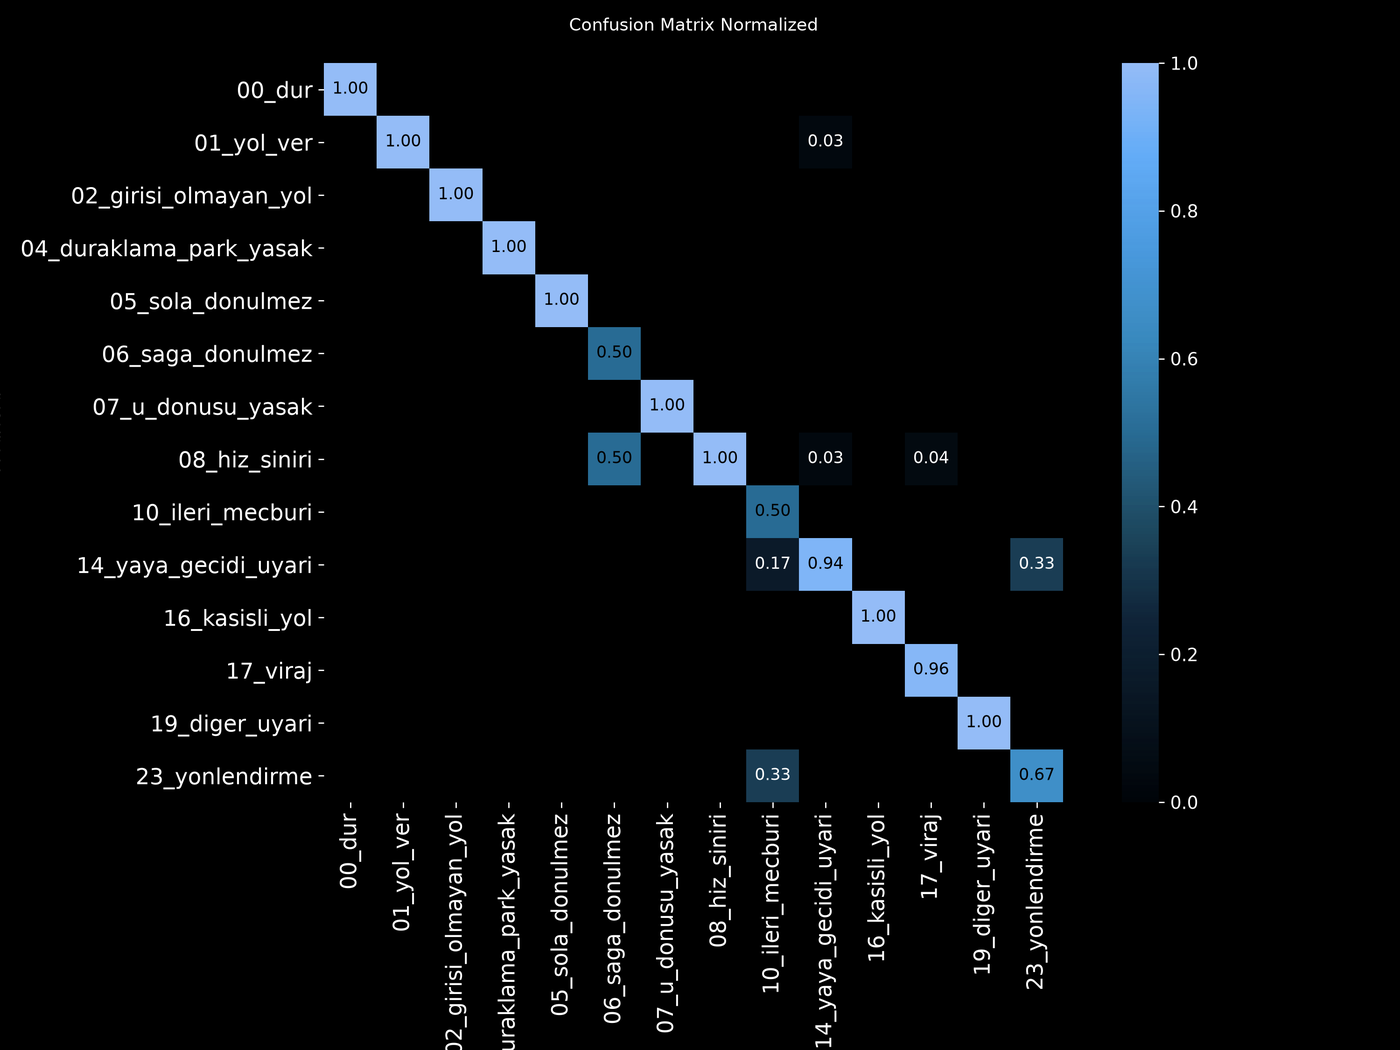
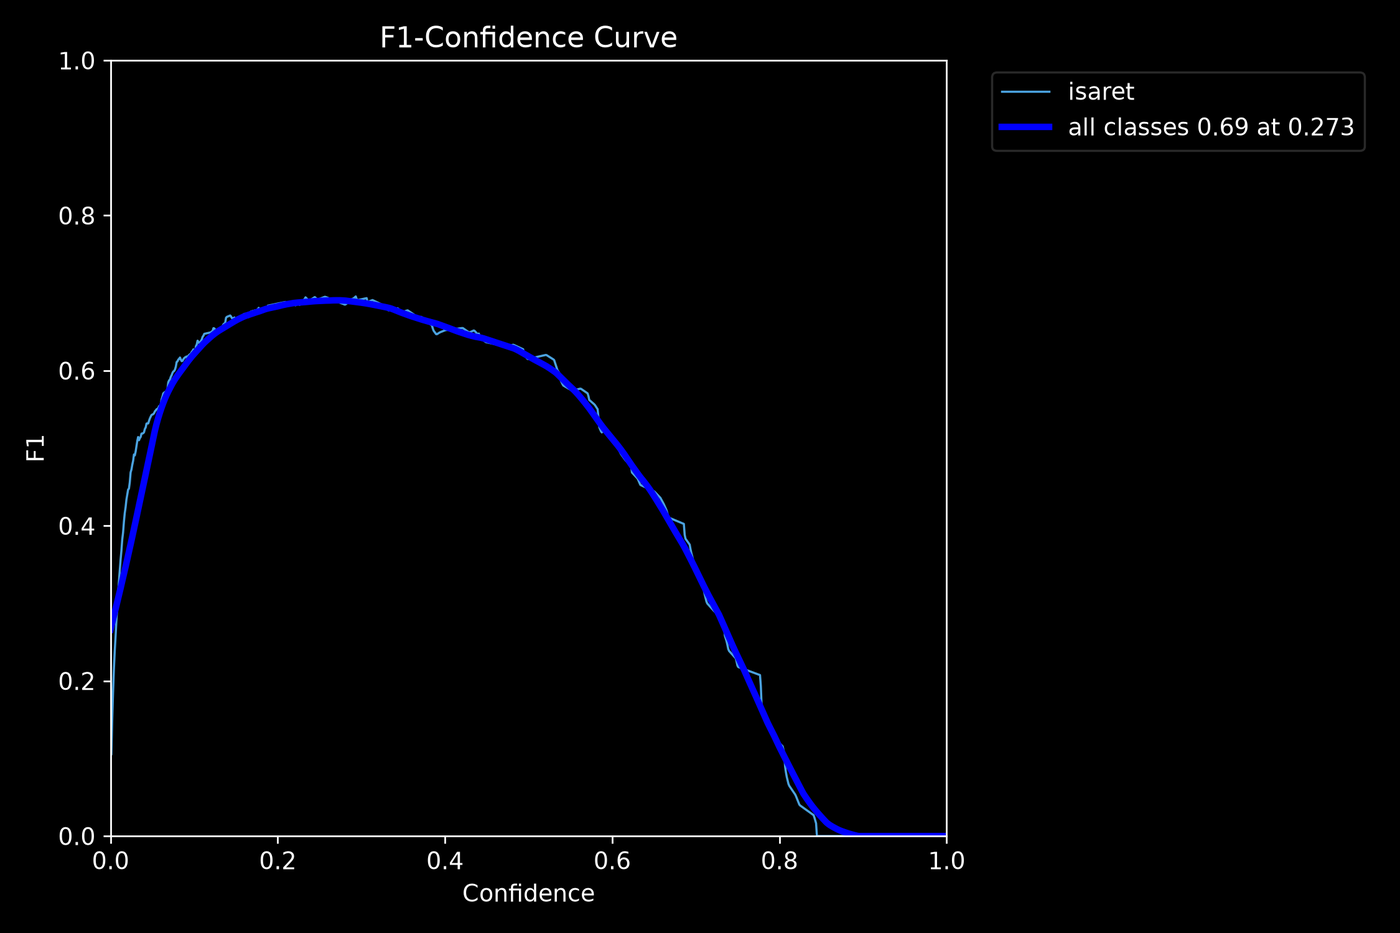
mAP50 is 0.515 across the test set, and the single number hides two different realities. Test kümesinde mAP50 0,515 ve bu tek sayı iki farklı gerçeği gizliyor.
Inference resolution mattered more than training did: running the 640-trained model at 960 px raised recall from 0.379 to 0.724 without retraining anything. At 1280 px it falls back to 0.448 — there is an optimum, and it does not show up without measuring. Çıkarım çözünürlüğü eğitimden daha çok fark yarattı: 640'ta eğitilmiş modeli 960 pikselde çalıştırmak, hiçbir şey eğitmeden duyarlığı 0,379'dan 0,724'e çıkardı. 1280 pikselde 0,448'e düşüyor — bir optimum var ve ölçmeden ortaya çıkmıyor.